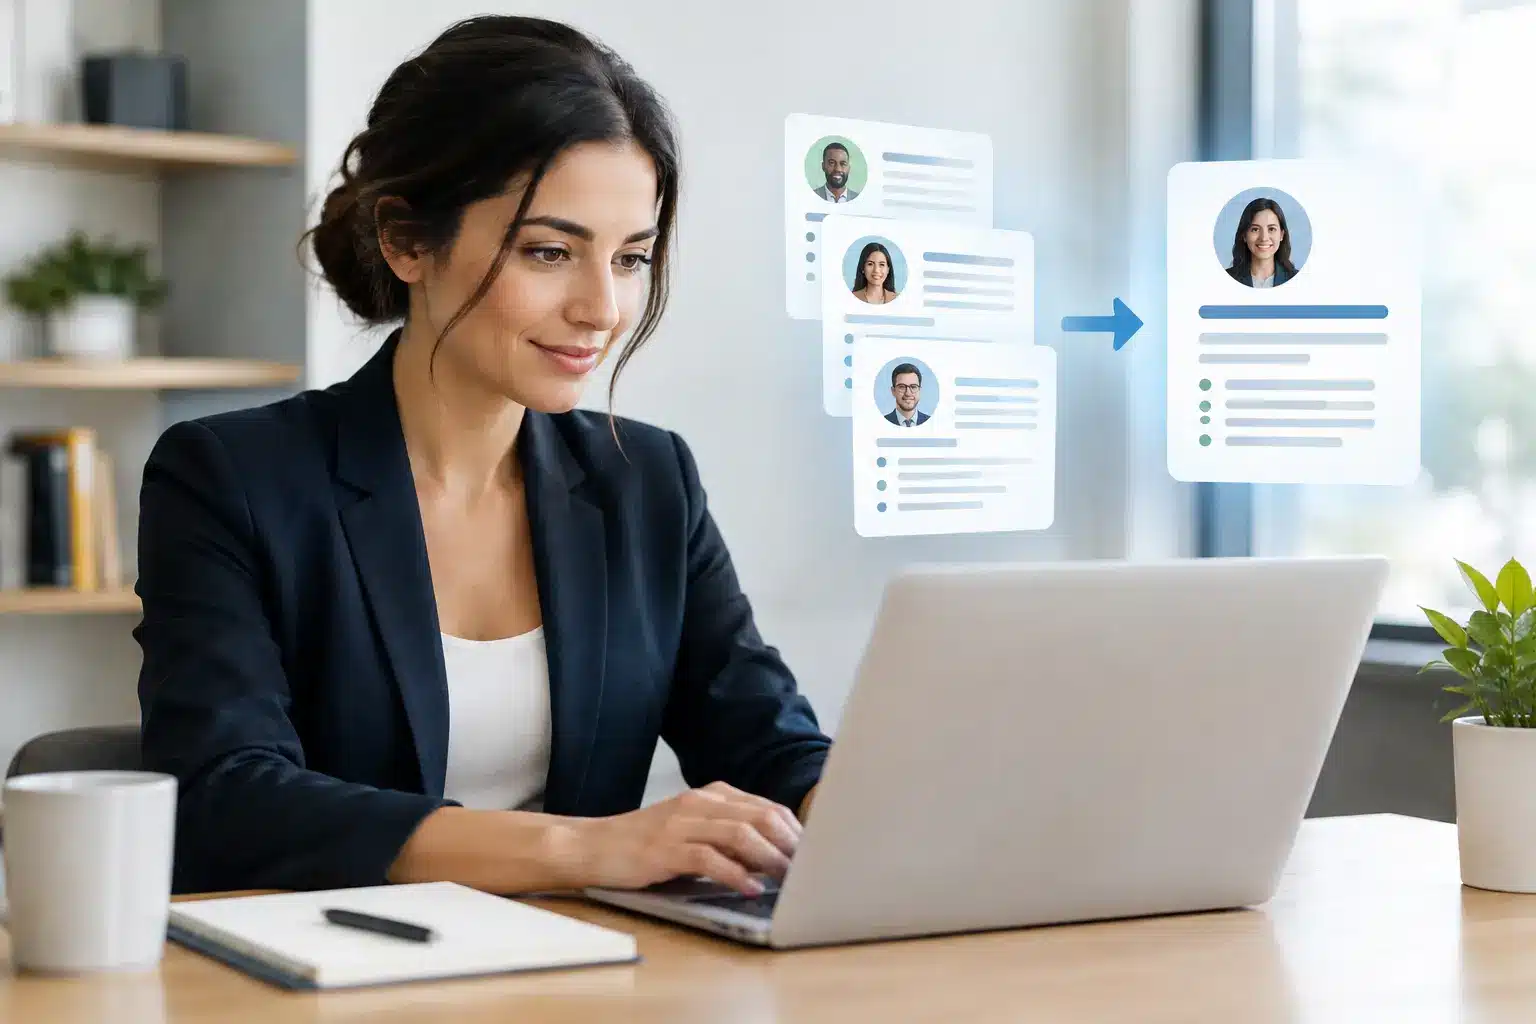

A recruiter should not have to read the same information three times: once in a resume, again while copying it into an ATS, and again when explaining a candidate to a hiring manager. Resume parsing eliminates that operational drag by converting unstructured candidate documents into data that can move through the hiring process.
That sounds simple. It is not. Weak parsing creates bad records, missed talent, and false confidence in automation. Strong parsing creates a usable candidate intelligence layer: structured profiles, searchable skills, standardized work history, and faster decisions without forcing recruiters to become data-entry clerks.
Hiring needs infrastructure – not another isolated feature. Resume parsing is one of the systems that determines whether your recruiting operation can operate at scale.
What Resume Parsing Actually Does
Resume parsing extracts information from resumes and converts it into structured fields. Depending on the system, those fields can include contact details, employment history, education, certifications, skills, languages, location, work authorization, and role-specific experience.
The operational value is not the extraction itself. The value is what happens next. Candidate data can be searched, filtered, ranked, routed into the right workflow, compared against job requirements, and carried forward into interview and offer processes without repeated manual work.
A resume is designed for a human reader. It may use columns, tables, creative formatting, abbreviations, inconsistent job titles, or a nonstandard order of information. A parser has to identify both the text and its meaning. It needs to recognize that “Account Executive,” “AE,” and “Enterprise Sales Rep” may describe closely related experience while still preserving the distinctions that matter for a specific role.
That is why basic keyword extraction is not enough. A list of words is not a candidate profile. Recruiting teams need context: how long someone used a skill, where they used it, at what level, and whether that experience matches the job in front of them.
Why Resume Parsing Breaks in Fragmented Hiring Stacks
Most teams do not have a parsing problem in isolation. They have a workflow problem.
A candidate applies through a job board. Their resume enters an ATS. A recruiter exports a spreadsheet for sourcing or reporting. Notes live in email, interview feedback sits in a separate platform, and the final offer is managed somewhere else. Even if the ATS parses the resume correctly, the candidate record starts to fragment the moment the process crosses into another tool.
The result is familiar: duplicate profiles, incomplete fields, inconsistent tags, lost notes, and recruiters who stop trusting the data. Once trust drops, teams return to inboxes and spreadsheets. Automation becomes optional, reporting becomes suspect, and hiring speed depends on who remembers what.
This is not a recruiter performance issue. It is an architecture issue.
Effective resume parsing should feed one candidate record that persists across sourcing, screening, pipeline management, interviews, feedback, offers, and compliance. The profile should become richer as the candidate moves forward, not more scattered.
Resume Parsing Should Improve Decisions, Not Just Speed
Speed matters, especially when qualified candidates are off the market quickly. But parsing that only accelerates sorting can create a more efficient version of the wrong process.
For example, a system may identify every applicant who has the word “Python” on their resume. That is useful for an initial search. It does not establish whether they built production systems, completed a short course, led an engineering team, or used Python five years ago. A recruiter and hiring manager need a signal they can act on, not a blunt match score.
The best approach combines structured extraction with job-specific interpretation. The system should identify relevant evidence, organize it against the role, and make the rationale visible to the team. Recruiters remain accountable for judgment. They simply stop spending their time on repetitive document handling.
That distinction matters for fairness, too. Resume formats vary widely by geography, industry, career stage, and personal preference. A parsing workflow should normalize information without treating formatting polish as a proxy for capability. If the parser cannot reliably interpret a file, it should flag the record for review rather than silently discard context.
The Data Fields That Matter Most
Not every field deserves equal weight. Collecting every possible data point can produce a crowded database with little decision value. The right structure depends on your hiring model, job families, geographies, and compliance requirements.
For most organizations, the highest-value fields are the ones that support action: current and past role titles, employers, dates of employment, skills in context, education or licensing where required, location, availability, and work authorization where legally appropriate. Candidate preferences and recruiter notes can be equally valuable, but they should be captured in governed fields rather than scattered across private messages.
Normalization is where the system earns its place. One candidate may write “Customer Success Manager,” another “CSM,” and a third “Client Success Lead.” A usable hiring system can recognize the relationship while preserving the original title. The same principle applies to skills, universities, certifications, and employer names.
Over-normalize, and you erase meaningful differences. Under-normalize, and search becomes unreliable. The goal is not perfect uniformity. The goal is reliable retrieval and defensible comparison.
Where AI Adds Value – and Where It Should Not Decide Alone
AI can strengthen resume parsing by handling variation that rule-based systems struggle with. It can infer skills from project descriptions, map adjacent titles to a role taxonomy, identify likely seniority, and surface relevant experience that a literal keyword search would miss.
It can also generate concise candidate summaries for recruiter review. Used well, this reduces the time required to understand a resume while keeping the source evidence available. A recruiter should be able to see why a candidate was surfaced, not receive an unexplained recommendation.
But AI should not become an opaque rejection engine. Candidates are more than a score, and resumes rarely contain the full picture. Career breaks, nontraditional paths, international experience, internal titles, and transferable skills all require judgment. Automation should prioritize work and reveal evidence. It should not hide the decision logic that affects people.
For regulated roles or high-volume hiring, governance becomes even more important. Define who can change matching criteria, what data is retained, how exceptions are reviewed, and how your team audits outcomes across applicant groups. Faster hiring is only a win if the process remains consistent, lawful, and credible.
How to Evaluate Resume Parsing in a Recruitment System
Do not evaluate parsing through a clean demo resume alone. Test the files your team actually receives: PDFs with unusual layouts, scanned documents, multi-page executive resumes, resumes from international candidates, and documents with gaps or unconventional career histories.
Ask whether the system preserves the original resume alongside the parsed profile. Ask how recruiters correct inaccurate fields, whether those corrections improve future results, and how data flows into search, screening, interview scorecards, and reporting. A parser that creates data trapped in one screen does not solve the operational problem.
You should also measure outcomes after deployment. Look at recruiter time spent on profile creation, percentage of records requiring correction, candidate rediscovery rates, time from application to first review, and the consistency of shortlist quality across recruiters. These measures reveal whether parsing is creating usable intelligence or merely generating more fields.
Dr.Job treats this capability as part of a connected recruitment operating system. Candidate information should enter once, inform every stage, and give recruiters a single source of truth instead of another database to maintain.
Build for the Candidate Record You Need Next Year
Resume parsing is often purchased as a convenience feature. That is the wrong frame. It determines the quality of the data that powers search, automation, reporting, and decision-making across your hiring operation.
Start with the hiring decisions your team needs to make faster and more consistently. Then build the candidate record, workflow, and governance around those decisions. When parsed data stays connected to the full recruiting lifecycle, your team spends less time translating resumes and more time recognizing the people who can move the business forward.