
A recruiter should not need to read 500 resumes just to find everyone with five years of SQL experience, an active CPA license, or authorization to work in a specific market. Yet that is still how too many hiring teams operate: opening files one by one, copying details into spreadsheets, and hoping qualified candidates are not buried in the pile.
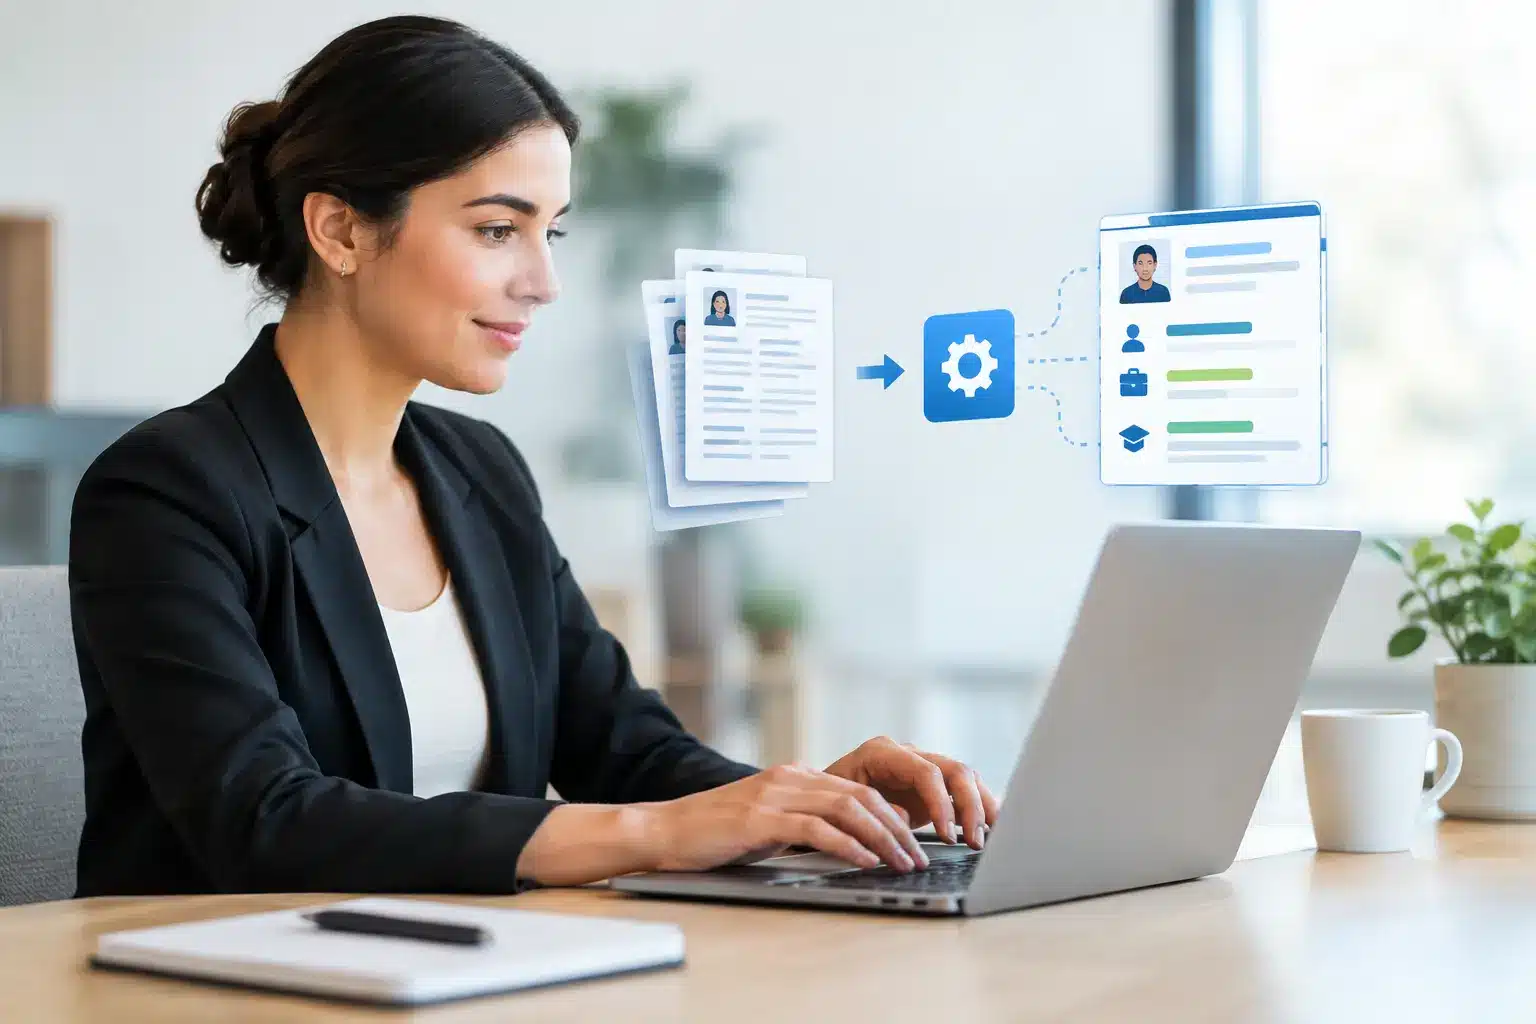
What is resume parsing? It is the technology that reads resume files and converts the information inside them into standardized, searchable candidate data. Done well, it turns an unstructured document into operational input for recruiting: fields your team can filter, compare, route, and use throughout the hiring workflow.
What Is Resume Parsing in Recruiting?
Resume parsing uses software, often supported by natural language processing and machine learning, to identify relevant details in a candidate’s resume. It extracts data such as name, contact information, work history, education, skills, certifications, job titles, employers, dates, locations, and languages.
The output is not simply a text copy of the resume. A parser attempts to recognize context. It should understand that “Python” is a skill, “Senior Data Analyst” is a title, and “January 2021 to Present” represents employment duration. It then maps those details into consistent fields within an applicant tracking system or recruitment platform.
That distinction matters. A folder full of PDF resumes is searchable only in limited ways. A structured candidate database lets recruiters identify people by experience, qualifications, availability, location, and role fit without manually rebuilding the same information for every applicant.
What a parser extracts
The exact fields vary by platform and resume format, but effective parsing typically captures personal and contact details, professional experience, education, technical and soft skills, certifications, links or portfolios, and inferred employment timelines. Some systems also normalize common variations, recognizing that “software engineer,” “software developer,” and related titles may belong to the same talent search.
Normalization is where the operational value begins. Candidates do not use identical language. One applicant may write “B.S.,” another “Bachelor of Science,” and a third may list only the university and graduation year. Parsing creates a more consistent record, but its accuracy depends on the quality of the parser and the complexity of the source document.
How Resume Parsing Works
The process starts when a candidate uploads a resume or a recruiter imports one from a sourcing channel. The system reads the file, whether it is a PDF, DOCX, plain-text document, or scanned image with usable text recognition. It identifies document sections, analyzes phrases and formatting, and assigns the extracted information to candidate profile fields.
Next, the platform standardizes the data. Dates are converted into a usable format, job history is separated into individual roles, and repeated skills can be consolidated. The candidate profile becomes a record that can be searched and used in workflow automation.
Finally, that structured data supports action. A recruiting team can match candidates to open roles, apply screening rules, trigger outreach, move applicants into the right pipeline stage, or assign profiles for review. Parsing does not hire anyone. It eliminates the administrative drag that prevents recruiters from focusing on hiring decisions.
Why Resume Parsing Matters at Scale
At low volume, manual review feels manageable. At scale, it becomes a bottleneck with a cost. Teams lose time re-entering data, candidate records become inconsistent, and strong applicants wait while recruiters work through intake tasks that software should handle.
Resume parsing changes the front end of recruiting from document management to data management. Instead of treating every application as a standalone file, the organization builds a searchable talent inventory. That improves speed, but speed is only one outcome.
Structured data also improves process control. Hiring leaders can see where candidates are in the funnel, which skills are most common among applicants, and whether sourcing channels produce qualified talent. Recruiters can revisit prior applicants when a new role opens rather than restarting the search from zero.
This is why parsing belongs in recruitment infrastructure, not as an isolated add-on. When candidate data enters one system and flows through screening, interviews, feedback, offers, and compliance workflows, teams reduce handoffs and avoid the fragmented records that make reporting unreliable.
Resume Parsing Is Not Candidate Evaluation
A common mistake is treating parsing as an AI hiring decision. It is not. Parsing organizes what a candidate has presented. Screening and assessment determine whether that information meets the requirements of a role. Human judgment determines whether the person is likely to succeed with the team and business.
That boundary is essential. A resume parser may identify “project management” as a skill, but it cannot reliably determine whether the candidate led a high-stakes transformation, coordinated a small internal project, or merely supported a project manager. Context still matters.
Parsing can also make mistakes. Resumes with unusual layouts, tables, graphics, text boxes, multiple columns, or scanned pages can confuse lower-quality systems. International resumes may use different date formats, naming conventions, academic credentials, and terminology. Candidates can use vague language, omit key details, or include outdated information.
The right operating model uses parsed data to accelerate review, not replace it. Teams should make the original resume visible alongside the structured profile, allow recruiters to correct fields easily, and avoid rejecting candidates solely because a parser failed to interpret a nonstandard document correctly.
What to Look for in Resume Parsing Software
The question is not whether a platform can extract an email address. Most tools can. The real question is whether the data becomes useful across your hiring operation.
Look for parsing that handles multiple file formats, recognizes varied resume structures, and produces clean fields that recruiters can edit. The platform should support search and filtering across parsed profiles, avoid duplicate candidate records, and preserve the original document for verification.
Integration matters, but consolidation matters more. If parsing exports data into an ATS, then recruiters copy it into a screening tool, then interview feedback lives somewhere else, the organization still has a workflow problem. The better model is a unified system where parsed candidate data drives the next step automatically.
For example, a qualified applicant can enter a role-specific pipeline, receive an initial screening request, and appear in recruiter search results without anyone moving data between tools. Dr.Job applies this system-level approach by connecting candidate intake to AI-driven screening, pipeline management, video interviews, offer workflows, and hiring records in one operating environment.
Where Resume Parsing Fits in a Modern Hiring Workflow
Resume parsing is most valuable at the point where candidate information becomes action. For inbound applicants, it removes repetitive intake work and creates consistent profiles from the start. For sourced candidates, it enables recruiters to add prospects to the talent database without manually filling every field. For existing applicant pools, it makes past candidates searchable when hiring demand changes.
Its value grows when the organization defines clear hiring criteria. A parser can surface experience, skills, location, and credentials. Your hiring process must specify which of those factors are required, preferred, or irrelevant for each role. Otherwise, faster intake simply creates a faster version of an unclear process.
The strongest teams pair structured resume data with structured evaluation. They use consistent scorecards, role-specific screening questions, and defined decision stages. Parsing gets the information into the system. A disciplined workflow turns that information into better decisions.
Hiring should not depend on who has time to open the next attachment. When resume data becomes structured, searchable, and connected to the full recruitment workflow, recruiters can spend more of their time on the work that actually moves hiring forward: assessing potential, engaging qualified people, and making decisions with confidence.